We’re thrilled to announce the launch of Minerva 2.0 🚀
If you’re building the fundamental data layer for automated business processes, or looking to enable AI agents to work accurately and cost-effectively, this release was built with you in mind.
Over the past months, one theme kept coming up in conversations with our customers and partners: the smartest agent or the most sophisticated automation is only as good as the data feeding it. Slow extraction, unreliable structure, high token costs, and fragmented security models do not just slow teams down, they quietly cap what automation and AI agents can actually achieve. Minerva 2.0 was built exactly for the purpose of removing those ceilings.
What’s New in Minerva 2.0
New Use Cases in Financial Services
We’ve expanded Minerva’s capabilities with several brand-new use cases purpose-built for financial services. Whether it’s underwriting documentation, compliance reporting, or onboarding paperwork, Minerva now covers more ground, immediately available for users.
Thousands of Simultaneous Extractions at 100x Speed
Scale has always been the bottleneck for document-heavy automation. With this release, Minerva can now run thousands of extractions simultaneously, at up to 100x the previous speed. Finally document extraction at scale is no longer a theoretical promise, it is a practical, production-ready capability, independent of the type and number of documents anyone wants to handle.
Obsidian-Level Security with Dedicated Data Repositories
Security isn’t a feature you bolt on, it is a foundational part of Minerva, especially when the data in question is sensitive, regulated, or business-critical. Minerva 2.0 introduces dedicated data repositories per user, giving every account its own isolated, obsidian-level secure environment. This is enterprise data security built for organizations that cannot compromise on where their data lives or who can access it.
Simplified and Renewed UX
Powerful infrastructure only matters if people can actually use it. We’ve rebuilt the interface from the ground up to be simpler, faster, and more intuitive, allowing teams to spend less time configuring and more time getting results.
And Many More New Features
On top of all the above, Minerva 2.0 ships with a long list of smaller refinements and additional features designed to make everyday workflows smoother, faster, and more reliable.
One Platform, Built for People and AI Agents Alike
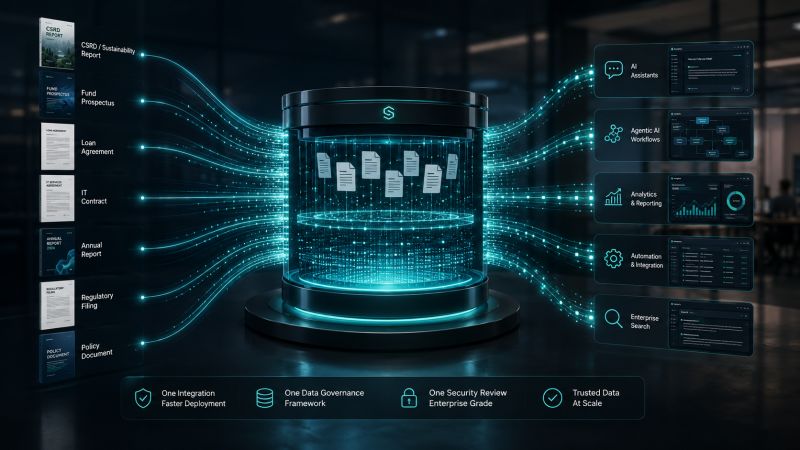
What makes Minerva 2.0 different isn’t any single feature, it’s that all of this now lives in one place, powering both human teams and AI agents from the same underlying data layer. As more of the enterprise stack shifts toward agentic workflows, this matters more than ever: agents need structured, accurate, low-cost data to reason over, and people need the same data to trust the outcomes.
This is precisely the gap Minerva is designed to close, serving as a reliable AI agent data infrastructure that both machines and humans can depend on. The result is a platform where extraction is fast to run at scale, secure for the most regulated industries, and efficient to keep low-cost token extraction within reach even as usage grows.
Shape the Future With Us
We’re opening a limited number of beta tester accounts in the coming days for teams who want to help shape where Minerva goes next. If you’re building automated business processes, deploying AI agents, or simply tired of your data infrastructure being the bottleneck, we would love to have you at the table.
Interested in becoming a beta tester? Get in touch with our team to learn more.